
What is bugbout?
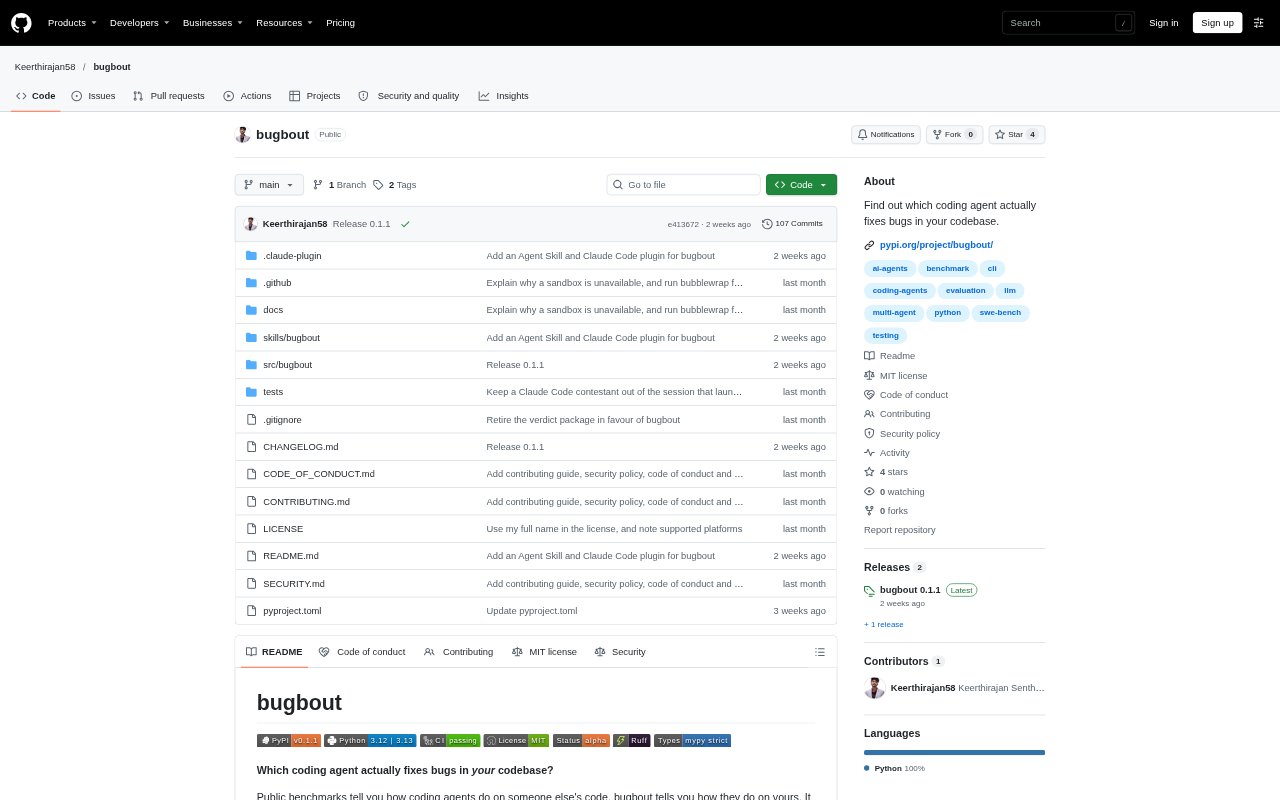
bugbout is a command-line tool for software teams that want to compare how coding agents repair bugs in their own repositories. It finds past fixes and related tests in Git history, runs configured agents against the code as it was before each fix, then judges and scores their patches. Developers can use the CLI or Python API to run a bout and create a Markdown report, with results tied to their project rather than a generic benchmark.
bugbout Features:
History Mining: bugbout turns fixes in Git history that reference an issue and add a test into tasks for an agent contest.
Hidden Tests: Tests that fail before the original fix and pass afterward define the expected repair, and agents do not see those tests.
Agent Support: The tool works with Codex, Claude Code, Gemini CLI, and mini-swe-agent, and supports other command-line agents through configuration.
Patch Cross-Examination: Tests written by each agent are run against every agent's patch, providing evidence that can be used to judge a fix.
Sandboxed Runs: Agents work in checkouts without Git history, inside an operating-system sandbox with web access disabled.
Resumable Reports: Bouts can be resumed after stopping, and the CLI can score results and render a report in Markdown.
bugbout Benefits:
Project-Specific Evidence: Teams can assess agents against their own code, conventions, and test suite instead of relying only on results from unrelated projects.
Grounded Scoring: Using tests associated with fixes the maintainers shipped gives teams a concrete basis for deciding whether a patch addresses a real bug.
Comparable Results: Running agents on the same set of historical tasks makes it easier to see where their repair attempts differ.
Safer Evaluation: Isolated checkouts without history or web access help teams evaluate agents without exposing the original fixes during a run.
Flexible Trials: Resumable runs and the option to add an agent later let teams continue a comparison without rerunning agents already tested.
Use Cases:
Agent Selection: A development team can run the same set of past bugs through several coding agents before choosing which to use in its workflow.
Model Comparison: Engineers can compare configured models, including local ones, on tasks drawn from their own repository.
Patch Review: A team can examine whether agents' own tests identify patches that fail when checked against other agents' fixes.
Repository Audit: Maintainers can use historical bug fixes to see how well coding agents handle the project's framework, code, and tests.
Evaluation Reporting: A developer can generate a Markdown summary of a completed bout to share or review the agents' results.