
What is llmspeed?
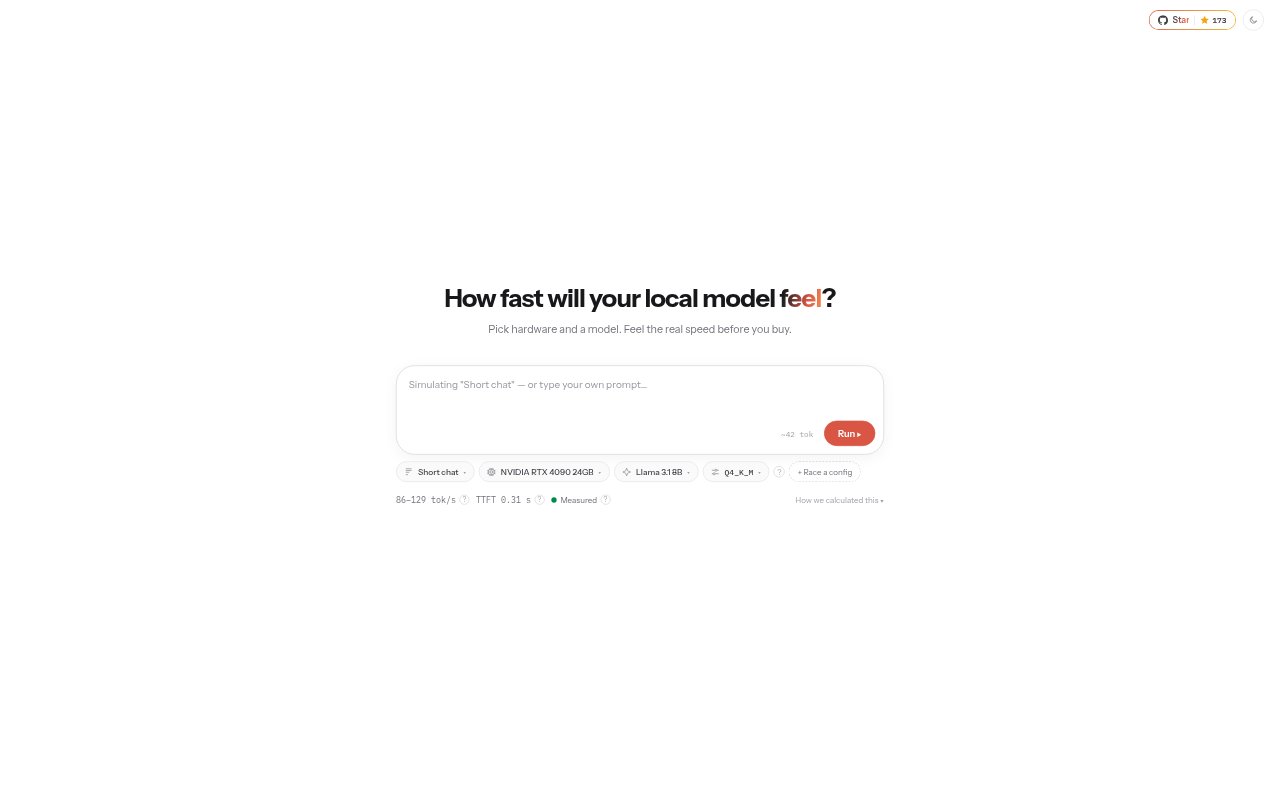
llmspeed helps people estimate how quickly local language models may run on different hardware before buying or setting up a device. Select a model and hardware option to view simulated token generation speed and time to first token for a short prompt on one device. The catalog covers GPUs, Macs, a CPU-only system, and cloud accelerators, giving people a way to compare possible local inference setups.
llmspeed Features:
Hardware Catalog: Browse options including NVIDIA and AMD GPUs, Apple Macs, a CPU-only system, and cloud H100 and H200 accelerators.
Model Catalog: Compare estimates for a selection of models, including Qwen, Gemma, GLM, DeepSeek, GPT-OSS, Llama, and Nemotron.
Speed Estimates: View simulated token generation speed in tokens per second for a selected model and hardware pairing.
First Token Timing: See an estimated time to first token alongside generation speed for a short prompt.
Benchmark-Based Data: Some estimates use community benchmark measurements, while others are derived from similar setups or projected from specifications.
Single-Device Estimates: The displayed estimates are for a short prompt running on one device, rather than a multi-device setup.
llmspeed Benefits:
Purchase Planning: Comparing estimated speeds can help you narrow hardware choices before spending time or money on a device.
Useful Speed Context: Looking at both token generation and first-token timing gives you more context than a single performance figure.
Model Tradeoffs: Checking several models against the same hardware can help you weigh speed alongside your other model preferences.
Broader Options: The mix of consumer, workstation, Mac, CPU, and cloud hardware makes it easier to explore more than one kind of setup.
Expectation Setting: Knowing whether an estimate is measured, derived, or projected helps you interpret it as a guide rather than a guaranteed result.
Use Cases:
GPU Research: Compare listed graphics cards for a chosen model while deciding which GPU to consider for local inference.
Mac Planning: Review estimates across listed MacBook and Mac Studio configurations before choosing a Mac for local models.
Model Comparison: Compare supported models on the same device when speed is one factor in choosing what to run locally.
Cloud Evaluation: Compare the listed cloud accelerators with local hardware when considering where a model might run.
Existing Hardware: Check a listed device you already own to get an estimate of its performance with a supported model.