
What is Lumabri?
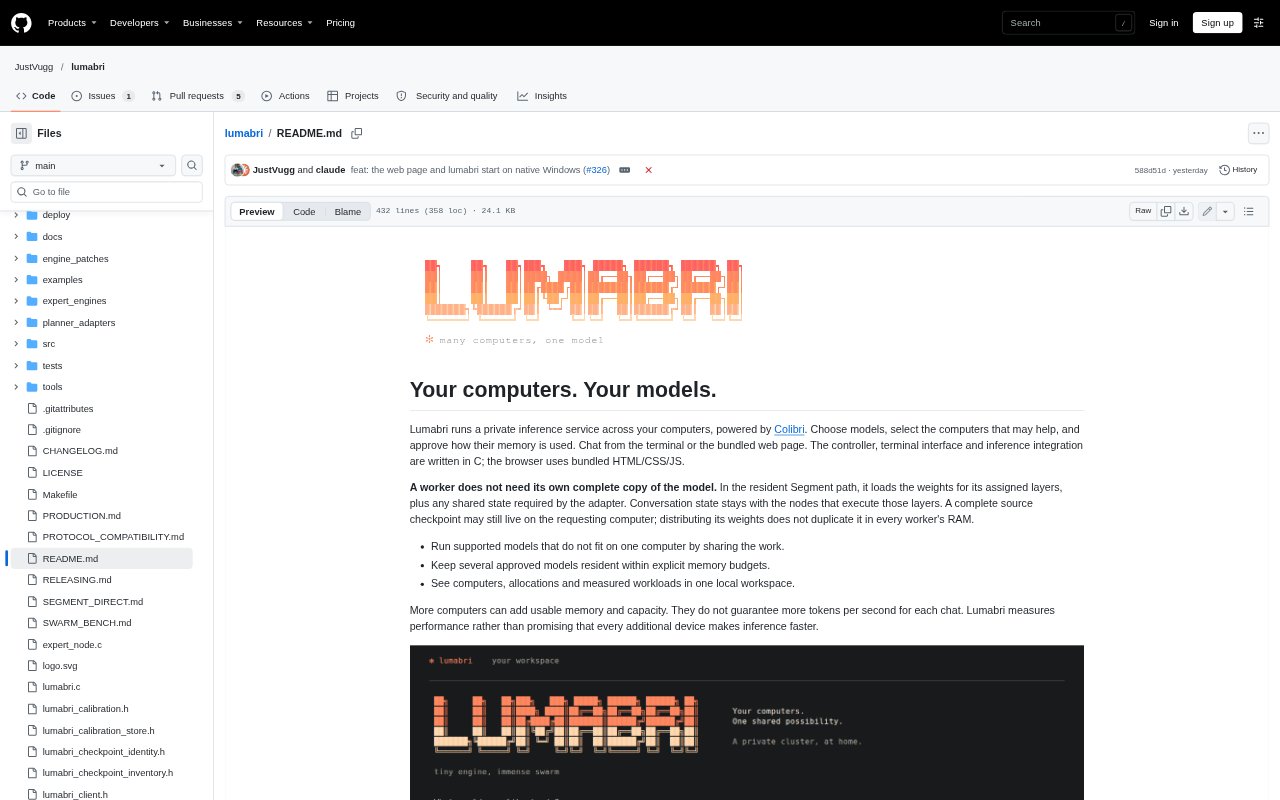
Lumabri runs a private inference service across computers on a household network, using Colibri to distribute model work across participating machines. It is for people who want to run supported models that exceed one computer’s available memory, while choosing which machines and models may take part. Chat is available from a terminal or bundled browser page, and prepared models can also be accessed through compatible APIs.
Lumabri Features:
Distributed Inference: Lumabri assigns contiguous model layer ranges to selected computers, so a supported model can use memory across several machines.
Resident Models: Computers can keep multiple approved model allocations resident within explicit memory budgets, with up to four allocations per donor.
Donor Approval: Each participating computer receives a request showing the model, layer range, RAM budget and disk headroom, and must approve before loading begins.
Resource Planning: The catalogue displays available RAM, detected hardware, model placement and missing resources before a plan is started.
Performance Checks: An optional short calibration measures observed speed for a selected computer and model combination, without promising long-run performance.
Compatible APIs: Prepared models can serve OpenAI Chat Completions, OpenAI Responses and Anthropic Messages requests, including streaming and function calls.
Lumabri Benefits:
Use More Memory: Combining approved computers can make supported models usable when their memory requirements exceed what one machine can provide.
Keep Control: Explicit donor approval and memory limits let participants decide which resources are shared and when a model is loaded.
Plan With Context: Reviewing placement and missing resources before starting helps identify whether a model can fit across the available computers.
Avoid Blind Estimates: Observed calibration results give users a measured indication of speed instead of treating hardware detection as a performance guarantee.
Reuse Model Capacity: Keeping approved allocations resident avoids having to prepare the same model again for every chat session.
Use Cases:
Run Larger Models: Distribute a supported model across household computers when its memory needs are too large for the requesting computer alone.
Share Home Hardware: Set RAM limits and approve selected household computers as donors for a private, locally managed inference service.
Try Terminal Chat: Start a conversation with a prepared resident model from Lumabri’s terminal workspace.
Chat in a Browser: Use the bundled browser page to open a conversation with an approved model on the local service.
Connect an Application: Point an application that supports OpenAI or Anthropic message APIs at a prepared model, with a token and authorized model ID.