
What is quantized.uk?
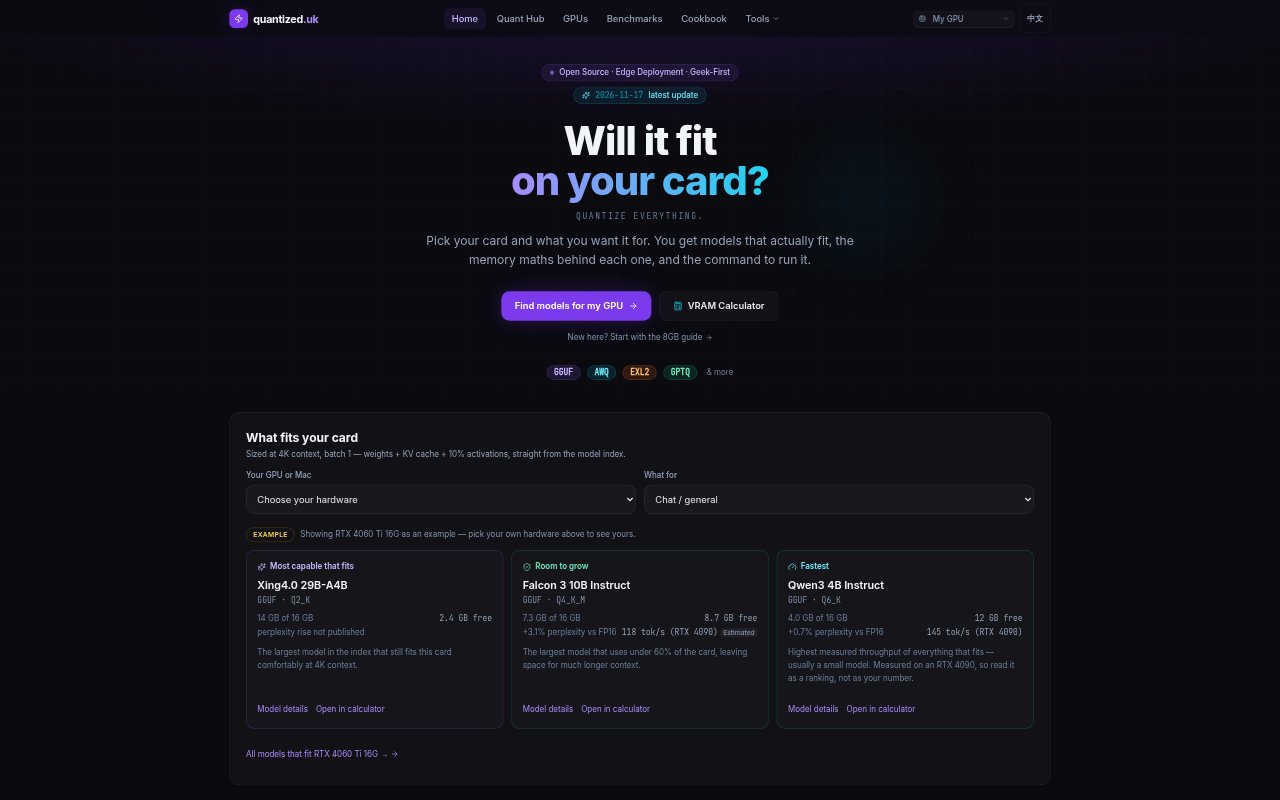
quantized.uk is a model-and-hardware reference for people who want to run quantized language models locally. Choose a graphics card, other listed hardware, or a task to find models that fit, along with their quantization levels and estimated memory use. The site also provides tools for comparing models, calculating VRAM needs, choosing a format, and generating commands for common runtimes. It is useful for local-model users deciding what their existing hardware can run.
quantized.uk Features:
Hardware Model Index: Browse 145 indexed models and filter by hardware, task, or requirements such as models small enough for an 8 GB GPU.
VRAM Breakdown: See memory estimates by model and quantization level, including weights, KV cache, and activation allowance at a stated context.
Hardware Verdict: The VRAM calculator checks a model, quantization, and context combination against hardware with a red, yellow, or green verdict.
Command Generator: Generate run commands for llama.cpp, Ollama, vLLM, or ExLlamaV2, either as a one-liner or Docker Compose.
Format Wizard: Answer three questions to get a recommendation for GGUF, AWQ, or EXL2 based on your needs.
Model Comparisons: Compare two models side by side across VRAM, speed, and quality to evaluate their trade-offs.
Benchmark Evidence: Review measured runs on real hardware alongside calculated estimates, with the measurement method and runtime versions provided.
quantized.uk Benefits:
Fewer Mismatches: Checking memory needs before downloading helps avoid choosing a model and quantization that exceed your available VRAM.
Clearer Trade-Offs: Seeing memory, speed, and quality together helps you decide which compromise suits your hardware and intended use.
Less Setup Guesswork: A generated command gives you a practical starting point for running a selected model with a supported runtime.
Better Context Planning: Accounting for context-related memory use can help you leave room for longer prompts rather than sizing only for model weights.
More Informed Estimates: Separating calculated figures from real-hardware measurements makes it easier to judge which performance claims need testing on your own setup.
Use Cases:
GPU Model Selection: A local-model user can check which models and quantization levels fit a particular NVIDIA, AMD, or Apple graphics setup.
CPU-Only Setup: Someone without a dedicated GPU can browse the index for models suited to listed system RAM configurations.
Longer Context Planning: Before using a model with a larger context window, check whether the extra KV-cache memory fits alongside its weights.
Runtime Setup: A user choosing between llama.cpp, Ollama, vLLM, and ExLlamaV2 can generate a command for the selected runtime.
Serving Model Choices: A team comparing two candidate models for local use can review their memory, speed, and quality side by side.