
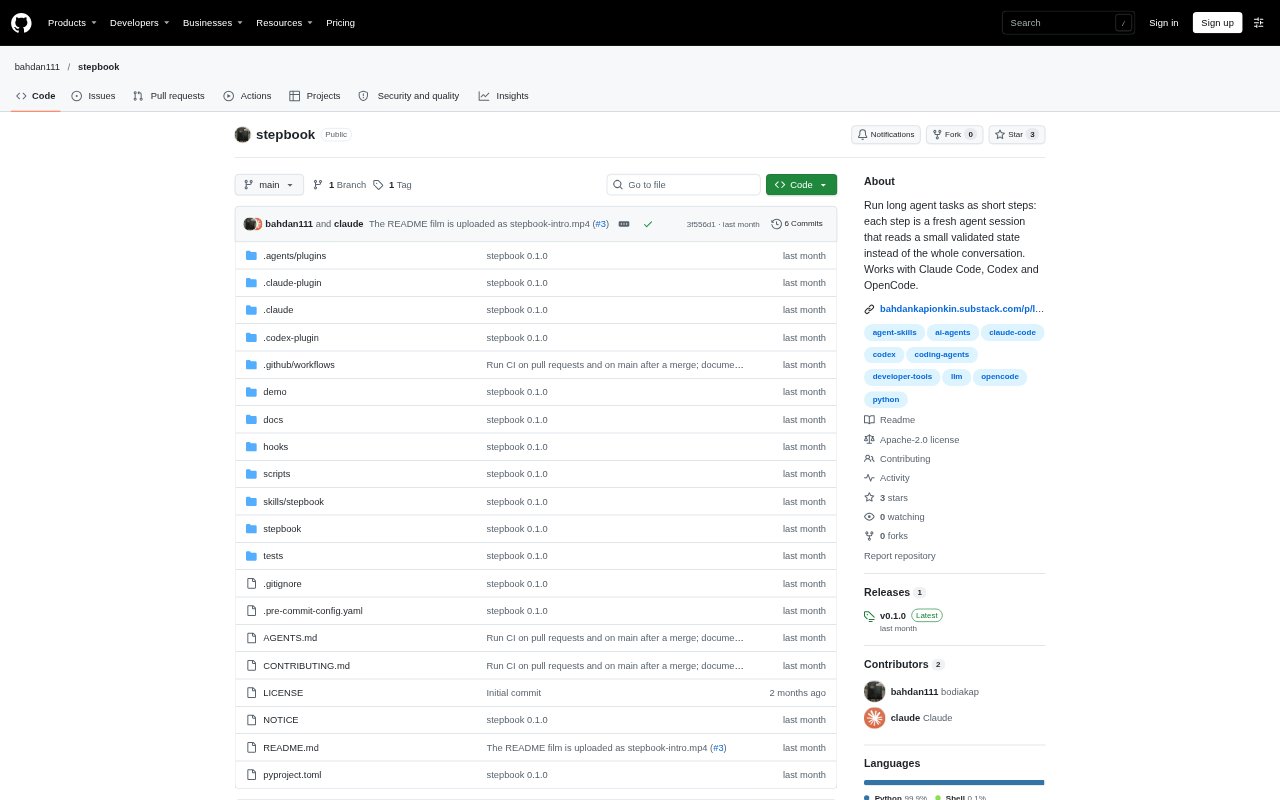
What is Stepbook?
Stepbook runs long coding-agent tasks as a sequence of short sessions, each guided by saved task state rather than the full conversation history. It is for developers and AI engineers who need agents to complete many steps toward a result they can check, such as passing tests or improving an evaluation score. It works with Claude Code, Codex and OpenCode, and includes built-in workflows for checklists and evaluation loops.
Stepbook Features:
Fresh Agent Sessions: Each step starts a new session with the task instructions, saved state and latest action result, rather than carrying forward the complete conversation.
Validated Task State: The agent proposes state changes that are checked against a skill schema and protected fields before they are saved.
Built-In Skills: Checklist, eval-loop and eval-loop-adapter skills cover long lists, score improvement and evaluation loops with computed comparisons and a run limit.
Run Journal: Stepbook records decisions, actions and results in a journal, then uses that record to resume a run without repeating completed work.
Git Branch Commits: Changes made during a run are committed to its own branch for review and merging, rather than being applied directly to the main working tree.
Run Controls: You can check status, send notes, pause or resume a run, and hand it to another supported agent.
Stepbook Benefits:
Less Session Oversight: Long tasks can keep moving through planned steps without requiring you to repeatedly prompt the agent to continue.
Lower Context Overhead: A fresh, state-based prompt avoids repeatedly processing the entire conversation history, which can matter over extended runs.
Recoverable Work: A stopped or interrupted run can continue from its journal, reducing the risk of losing the decisions and progress already made.
Reviewable Changes: Keeping run changes on a separate branch makes it easier to inspect the work before deciding whether to merge it.
Flexible Handoffs: A run can move between supported agents, so progress does not have to depend on keeping one agent session alive.
Use Cases:
Test Suite Repairs: Ask an agent to work through failures after a framework upgrade, using a test command as the check for completion.
Codebase Migrations: Use a checklist to migrate call sites or services one by one, with commands that confirm the work remains green.
Documentation Updates: Give an agent a defined list of documentation pages to update and let it work through each item to its done condition.
Evaluation Tuning: Run repeated experiments on a RAG system or another project, keeping or reverting changes based on evaluation results.
Prompt Iteration: Use an evaluation loop to try prompt changes and compare their measured results across a series of experiments.