
What is Strim?
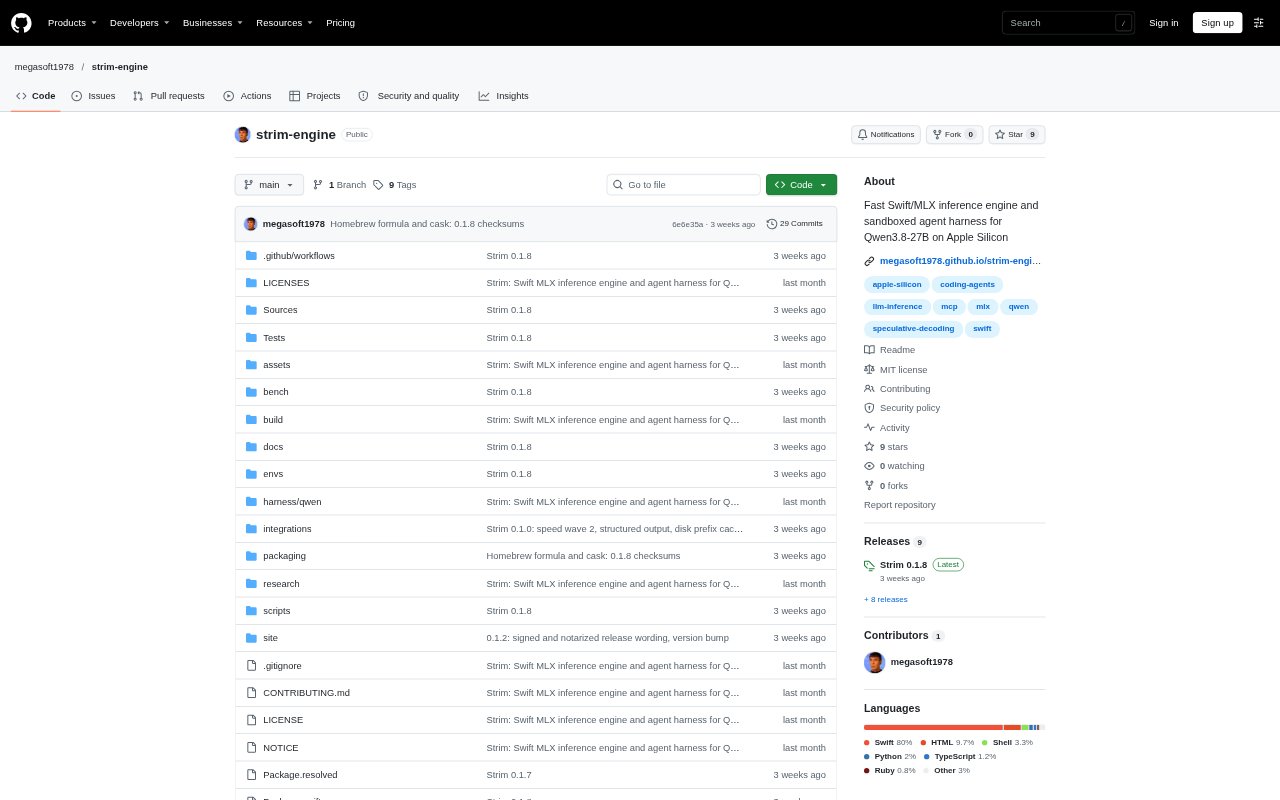
Strim is a local model server and sandboxed agent harness for running Qwen3.8-27B on Apple silicon Macs. It is aimed at developers who want coding agents to use a model served from their own machine, including users of Claude Code and Codex. The product includes a command-line tool and an optional menu-bar app, and runs as a Swift binary on macOS 14 or later.
Strim Features:
Local Model Serving: Serve the Qwen3.8-27B model on an Apple silicon Mac, with inference kept on the local machine.
Agent API Endpoints: Expose local endpoints configured through Anthropic and OpenAI base URL environment variables for compatible coding-agent workflows.
Command-Line Control: Use the strim CLI to download the model and start the server with selected model paths and a port.
Menu-Bar App: Install an optional menu-bar app that includes the CLI and provides a popover for viewing server activity.
Live Status Metrics: View live decode speed, memory use by component, and engine counters in the status window.
Sandboxed Agent Harness: Run coding-agent work through a sandboxed harness built alongside the Swift and MLX inference engine.
Strim Benefits:
Private Workflows: Keeping model inference on the Mac helps teams handle code and prompts without sending them to a remote model service.
One Local Setup: A CLI, server, and optional menu-bar app give developers a single local setup for serving the model and checking its activity.
Visible Resource Use: Live speed and memory figures make it easier to see how the model is using the Mac during agent work.
Agent Compatibility: Anthropic- and OpenAI-style endpoint settings let developers connect supported agent workflows to a model on their own machine.
Focused Model Choice: A dedicated Qwen3.8-27B setup suits developers who want to run this model rather than browse a large model catalogue.
Use Cases:
Claude Code Sessions: Point Claude Code at Strim's local Anthropic-compatible endpoint when using Qwen3.8-27B for coding-agent tasks.
Codex Workflows: Configure Codex to use the local OpenAI-compatible endpoint for agent work on an Apple silicon Mac.
Local Model Testing: Start the server from the CLI to test how Qwen3.8-27B responds in a local development workflow.
Agent Resource Checks: Watch decode speed and component memory while coding-agent jobs run to understand their load on the Mac.
Mac-Based Inference: Download the model and run inference locally for development work that should keep prompts and code on the machine.