
What is UnbiasedStrata?
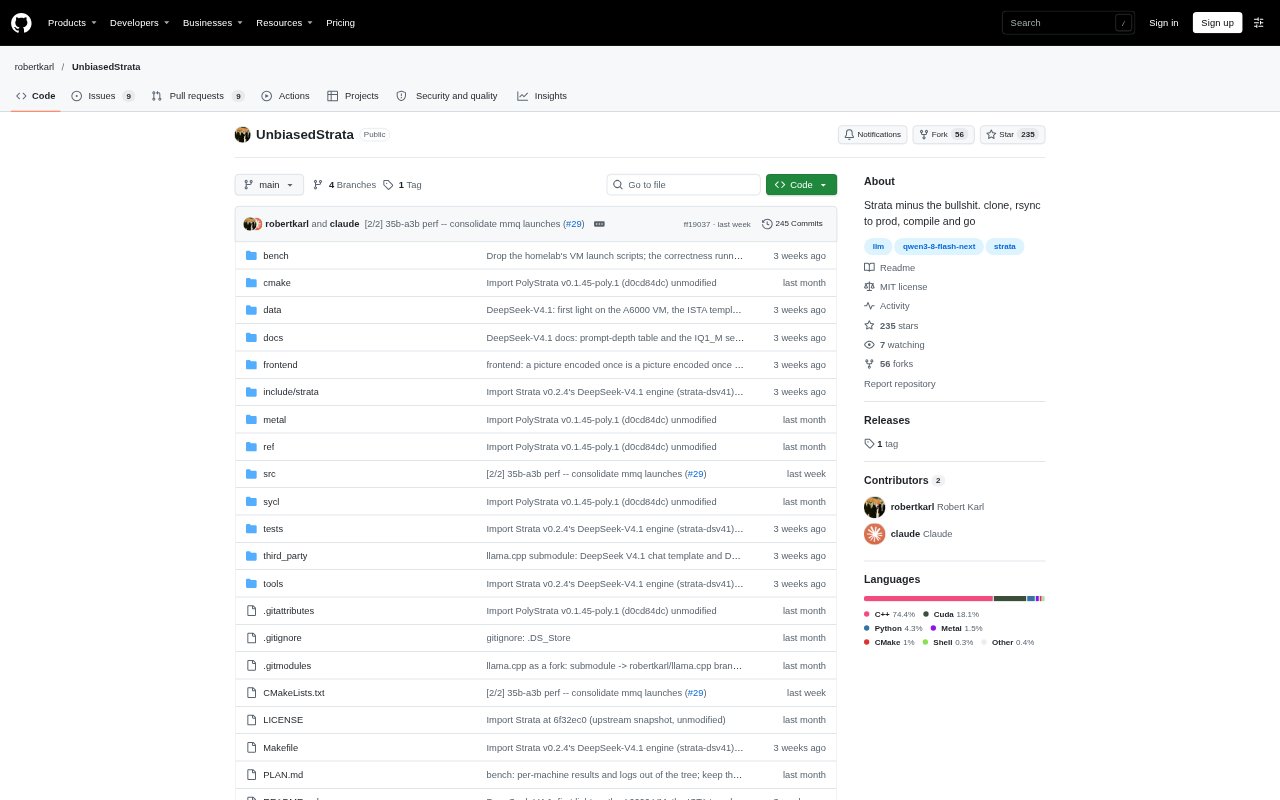
UnbiasedStrata is a Linux inference server for running Strata-family language models on NVIDIA GPUs. It combines Strata engines with a C++ front end based on llama.cpp server code, exposing an OpenAI-style chat API and related endpoints. It is aimed at developers and operators who want to build and run local model inference, including on machines that are kept offline. The project is a fork of PolyStrata, with its inference engines retained and the surrounding build and serving setup replaced.
UnbiasedStrata Features:
Engine Selection: Choose among the strata, strata-poly, and strata-dsv41 engines, or supply a path to another engine executable.
Chat API: The server provides streaming and non-streaming chat completions, plus model listing, health, tokenization, detokenization, and properties endpoints.
Server Options: Pass options such as host, port, API key, alias, sampling settings, and reasoning format to the llama.cpp-based front end.
Image Input: With a model projector, the front end encodes pictures using llama.cpp's mtmd code, checks projector width at startup, and sends image rows to the engine.
Local Build: A make build command compiles the engines and front end on Linux, while make test exercises the front end with a fake engine without requiring a GPU or model.
Offline Model Setup: Model files can be prepared on a networked machine and copied to the inference host, where the project does not download models at build or startup.
UnbiasedStrata Benefits:
Fewer Runtime Dependencies: Keeping Python out of the request-to-token path means operators have fewer runtime components to install and maintain.
Disconnected Serving: Once model files are transferred, inference can run on a host with no network access.
Existing Client Fit: The OpenAI-style API gives chat clients that use this format a familiar way to send requests and receive responses.
Accessible Testing: The fake-engine test lets developers check the front end before arranging access to a GPU or model files.
Local Control: Running inference on the operator's own GPU machine keeps model execution within the environment they manage.
Use Cases:
Local Chat Hosting: Run a GGUF language model on a Linux NVIDIA machine and expose chat completions to an application on the same network.
Offline Inference: Serve a model in a disconnected environment after transferring its files and any required packs to the host.
Image-Aware Prompts: Send dashboard screenshots or other pictures alongside a prompt when the selected model and engine support vision.
Engine Evaluation: Use the included benchmark and correctness tooling to examine inference behavior against llama.cpp or upstream PolyStrata.
Front-End Development: Build changes to the server front end and run its fake-engine test without loading a real model.