
What is EvalCart?
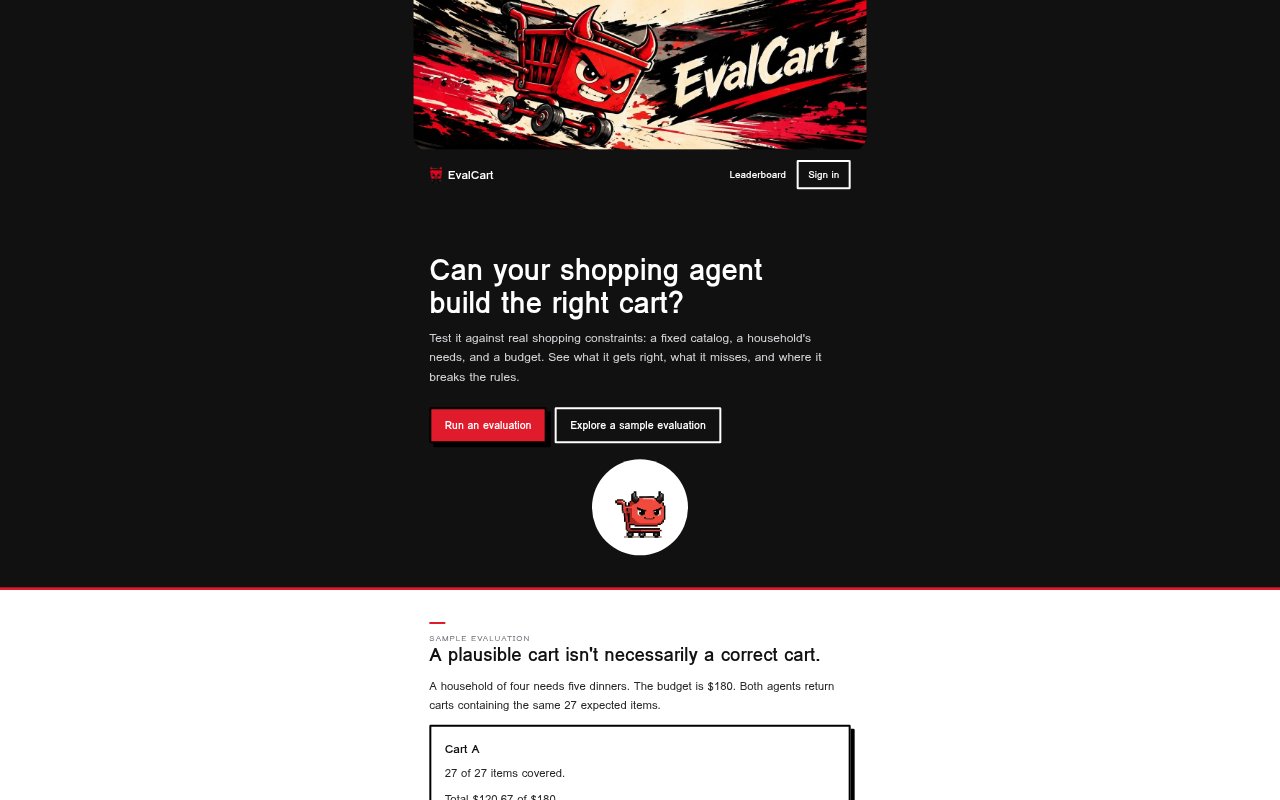
EvalCart is a benchmark for testing grocery-shopping agents against household requirements, a fixed product catalog, and a budget. It gives developers, product managers, and researchers a shared way to evaluate agent-generated carts, inspect failures, and compare results across runs. Evaluations use synthetic scenarios and a deterministic scorer; the tool does not connect to grocery retailers or place real orders.
EvalCart Features:
Frozen Catalog: Every agent works with the same fixed grocery catalog, giving evaluations a consistent set of products to choose from.
Household Tasks: Tasks specify household needs, a budget, and how pantry items or leftovers should be handled.
Deterministic Scoring: A deterministic scorer checks each cart against task criteria and provides receipts that evaluators can inspect.
Constraint Checks: Going over budget or breaking a hard constraint fails a run, while efficiency is reported separately from quality.
Run Comparison: Submitted agent runs can be compared on the same shopping tasks, with scores, hard failures, and transcripts when available.
Evaluation Options: Users can score a cart through the API, submit an agent run, try the test store, or create and save custom evaluations.
EvalCart Benefits:
Repeatable Tests: A shared catalog and task set make it easier to tell whether an agent change improved results or introduced new problems.
Visible Failures: Scores and checked receipts help teams identify specific mistakes, such as missing ingredients, unwanted substitutes, or excess spending.
Less Setup: Teams can evaluate shopping behavior without first building their own benchmark, product catalog, and scoring process.
Focused Comparisons: Using identical conditions makes differences between agent implementations easier to examine than comparing unrelated shopping tasks.
No Real Orders: Synthetic scenarios let teams test cart decisions without spending money, connecting a grocery account, or placing retailer orders.
Use Cases:
Agent Development: Developers can run the same household task before and after changing an agent to check whether its cart decisions improved.
Release Tracking: Product managers can compare evaluation results between releases and review which constraints a new version handles poorly.
Research Comparisons: Researchers can submit different shopping-agent implementations against shared tasks and inspect their scores and failures.
Budget Testing: Teams can check whether an agent builds a household's requested grocery cart without exceeding its stated budget.
Custom Scenarios: An evaluator can set household requirements, a budget, and pantry or leftover rules, then save the task for later reruns.