
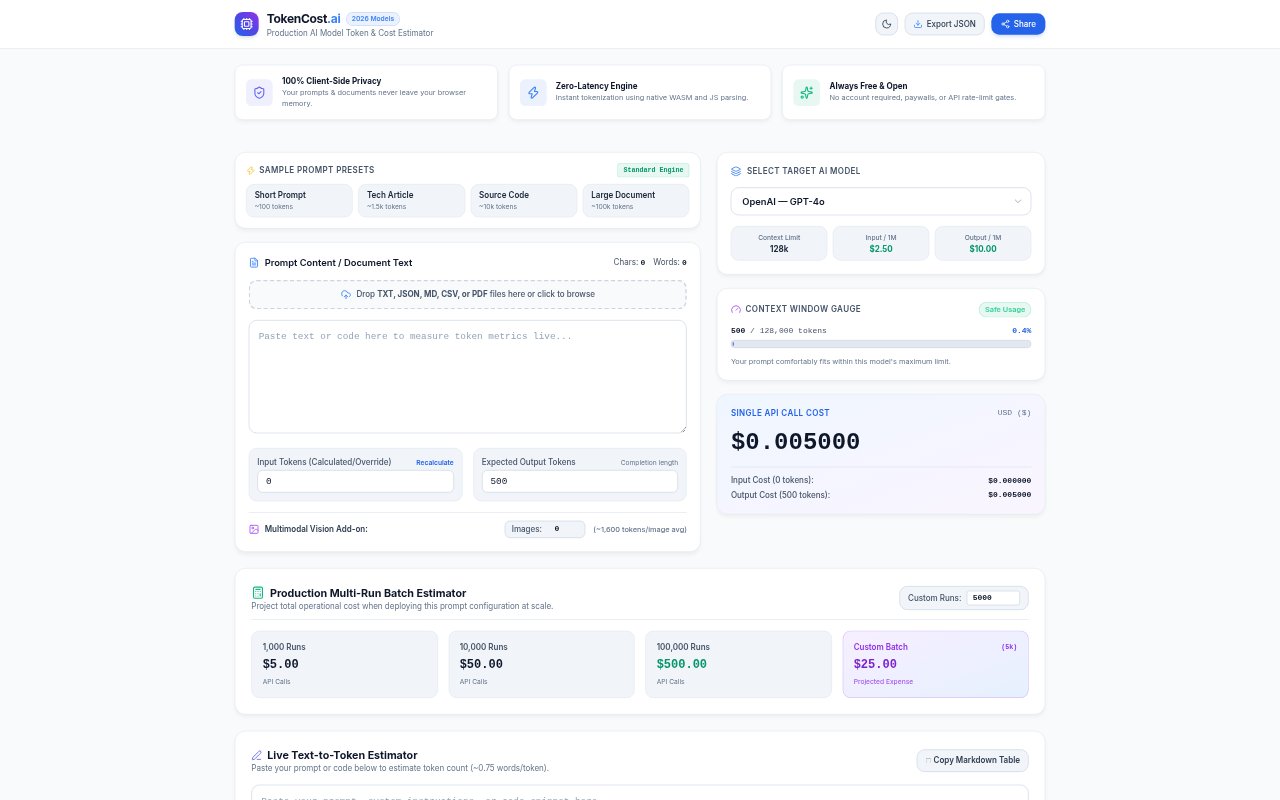
What is TokenCost.ai?
TokenCost.ai is a browser-based estimator for developers working with language model APIs. It calculates token counts for prompts and code, estimates API costs, and helps check how much of a model’s context window a request may use. The tool covers models from OpenAI, Anthropic, Google, and DeepSeek, with options to upload documents and compare model metrics. Calculations run locally in the browser, and the tool can be used without an account.
TokenCost.ai Features:
Live Token Counts: Paste text or code into the estimator to see its approximate token count.
Document Uploads: Upload documents for local parsing and token or context estimates.
API Cost Estimates: Estimate request costs using input and output pricing for models from OpenAI, Anthropic, Google, and DeepSeek.
Context Window Checks: Estimate context usage and check a prompt against a model’s capacity limit.
Model Comparison: Compare model providers, context limits, and input and output rates in a side-by-side matrix.
Batch Cost Planning: Project costs for repeated runs, with estimates for a single API request and a 100,000-run batch.
TokenCost.ai Benefits:
Private Estimation: Keeping prompt text and uploaded files in the browser lets developers assess sensitive material without sending it to an external processing server.
Fewer Capacity Surprises: Checking context usage before making a request can help teams spot prompts that may exceed a model’s limit.
Clearer Budgeting: Separate input and output estimates help developers account for both parts of an API request when planning spend.
Model Decisions: Seeing model limits and rates together makes it easier to weigh cost and capacity when choosing where to send a prompt.
Lower Setup Friction: Using the estimator without an account makes it straightforward to check a prompt before deciding on a model or deployment plan.
Use Cases:
Prompt Review: Check the token size of a system prompt or code snippet before sending it to a language model API.
Provider Selection: Compare model rates and context limits when deciding which provider to use for a particular prompt.
Batch Forecasting: Estimate the cost of repeatedly running a prompt configuration as part of a production workload.
Document Preparation: Upload a source document to gauge its token and context impact before including it in a model request.
Request Budgeting: Review estimated input and output costs while planning the budget for an API request.